Speaker diarization: label who said what in interviews
Speaker diarization splits a recording by voice. Learn what it gets wrong, then name the speakers and fix who said what in your transcript.
Published
Speaker diarization answers the question “who spoke when”. A diarization model splits a recording into turns and groups the turns by voice. It labels the groups Speaker 1, Speaker 2 and so on, because it knows voices, not people. You give the speakers their names, then check the transcript against the audio wherever the speaker changes.
This guide uses TrueScribe on Windows or Linux, where diarization is called speaker detection. It is part of TrueScribe Pro and runs on your computer.
Transcription and diarization are two jobs
Speech recognition turns sound into words. Whisper, the model TrueScribe uses for transcription, handles speech recognition, translation and language identification. Its transcript does not say who is speaking.
A diarization model listens to the voices instead of the words. TrueScribe runs it after transcription and assigns each transcript segment to a speaker. Where the speaker changes in the middle of a segment, TrueScribe can split the segment at the change.
Where diarization goes wrong
pyannote.metrics, a toolkit for evaluating diarization, counts three kinds of error:
- Missed detection. The model treats speech as silence.
- False alarm. The model treats silence or noise as speech.
- Confusion. The model hears the speech but credits it to the wrong speaker.
In an interview transcript, confusion is the error you notice. A question shows up under the guest’s name. Overlapping speech is a known weak spot. The pyannote.metrics paper notes that overlap can increase missed detection when a system does not detect it. When you review, start with the places where both people talk at once and with very short replies.
Identify the speakers
- Open the transcript in TrueScribe.
- In the Speakers panel in the sidebar next to the transcript, leave Speaker count on Auto.
- Select Identify speakers.
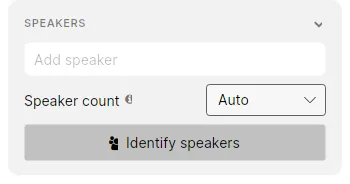
The first run downloads the diarization model. TrueScribe reuses it offline after that, and the recording stays on your computer.
To skip this step for future recordings, open Preferences, go to Transcription and turn on Identify speakers automatically. TrueScribe then runs speaker detection after each new transcription.
Name the speakers
Click a name such as Speaker 1 in the Speakers panel, type the new name and press Enter. Every segment of that speaker takes the new name.
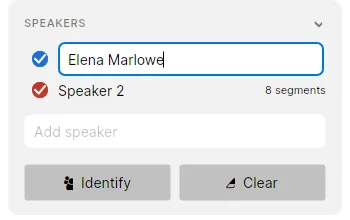
For research interviews, use the codes from your study, such as “Interviewer” and “P07”, rather than real names. The guide on transcribing research interviews under GDPR covers pseudonymisation in more detail.
Fix who said what
Play the recording and read along. When a segment sits under the wrong name, right-click it, open Assign speaker and pick the right person. The change applies to that one segment, and undo reverses it.
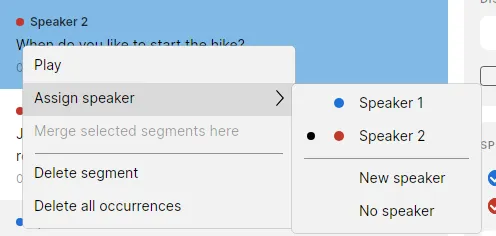
The same menu covers the other common mistakes:
- A voice the model missed. Choose New speaker to add a label for it, then rename the label.
- One person under two labels. Assign the segments of the extra label to the right person. Then right-click the empty label in the Speakers panel and choose Delete speaker.
- Noise or music credited to someone. Choose No speaker.
To review one person at a time, clear the checkbox next to the other names in the Speakers panel. Their segments disappear from the list until you tick the box again.
Export with speaker names
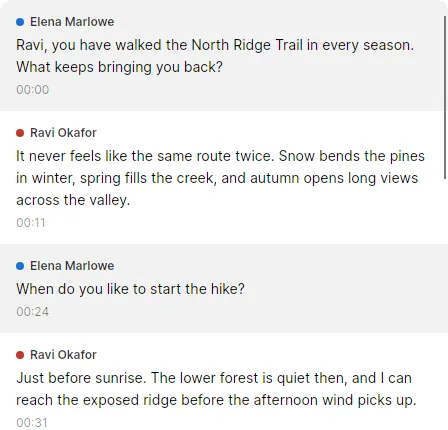
Select Export and choose Segments under Content. Each segment then carries its timestamps and the speaker’s name. The Complete option exports flowing text without speaker names.
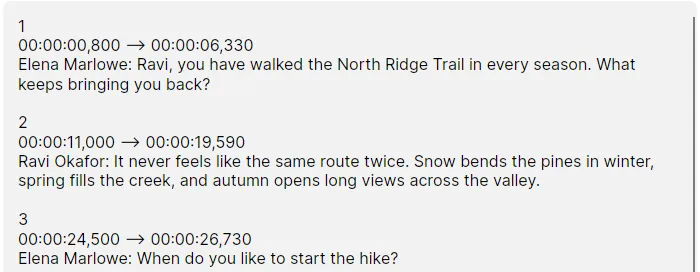
TXT, SRT and WebVTT export works in every version of TrueScribe. Pro adds documents and structured data for the next step in your workflow.
Download TrueScribe to try it, see what Pro includes, or compare it with noScribe, another local transcription app with speaker detection.